Clockwork.io Raises $31M to Reduce Costly GPU Downtime in AI Infrastructure
Top Picks
Submit PR
Stay Ahead of the Market
Get the latest startup funding, hiring trends and global opportunities delivered to your inbox every week.
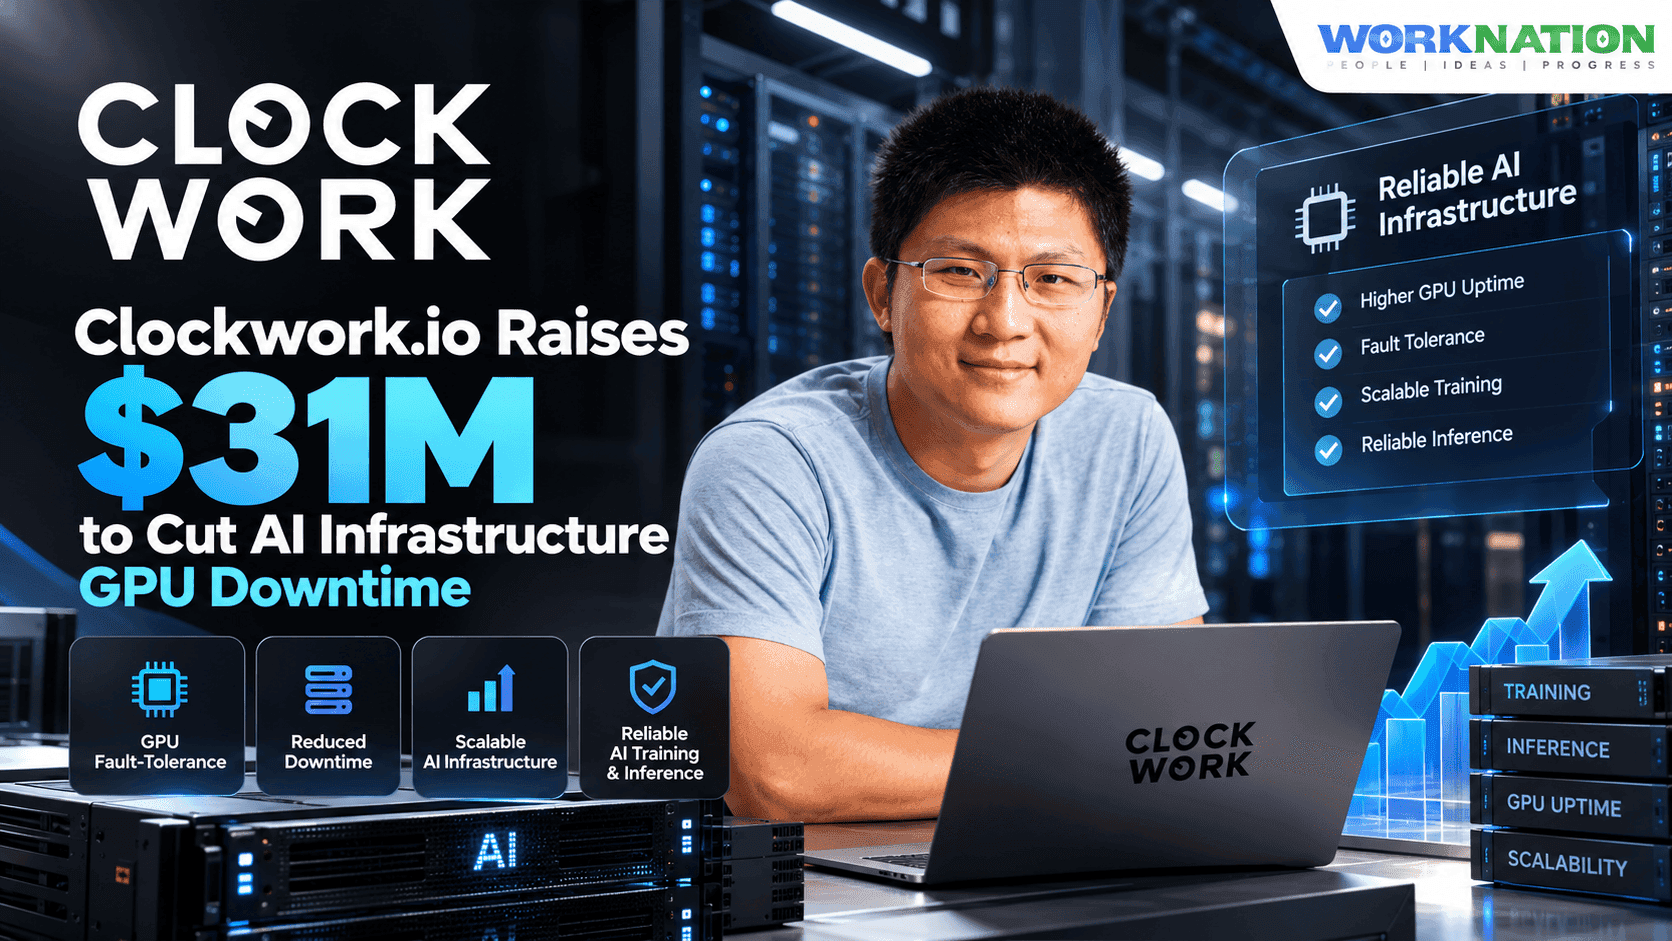
AI infrastructure startup Clockwork.io has raised $31 million in new funding to help AI cloud providers and enterprises reduce costly GPU downtime. The round was co-led by Premji Invest, Wing Ventures and Seligman Ventures, with participation from existing investors NEA and e& Capital. The financing brings the company's total capital raised to $73 million.
Founded in 2018 from research at Stanford University, Clockwork.io develops software that helps large AI workloads recover from hardware and network failures without repeatedly restarting entire jobs. Its technology targets a growing challenge for companies running large GPU clusters: even a single component failure can interrupt thousands of processors and waste hours of completed computing work.
The new funding will support the expansion of Clockwork's fault-tolerance platform across AI training, inference and reinforcement learning.
Why GPU Downtime Is Becoming More Expensive
Training and operating large AI models requires clusters of GPUs working together across servers and networks. These systems can run complex jobs for hours or days, making reliability a major operational concern.
When a GPU, network link, network interface card or server fails, the impact can extend beyond the affected component. Depending on the workload and its recovery design, a failure may force a distributed training job to restart from an earlier checkpoint.
That means previously completed work can be lost, while otherwise healthy GPUs remain idle during recovery.
The scale of the problem grows as clusters become larger. The article cites Meta's experience during a 54-day Llama 3 training run involving 16,384 GPUs, during which unexpected interruptions occurred roughly every three hours.
For AI infrastructure providers, downtime affects more than hardware availability. It can reduce the amount of useful computing work delivered from expensive GPU fleets, increase operating costs and delay the completion of AI workloads.
Clockwork.io is building software to address these failures at the infrastructure level.
How Clockwork.io's Fault-Tolerance Platform Works
Clockwork's platform is designed to help distributed AI workloads continue operating when infrastructure components fail.
Rather than relying entirely on traditional checkpoint-and-restart methods, its software provides mechanisms for rerouting traffic, moving workloads away from failing GPUs and preserving the state of running jobs.
The company's product portfolio includes LinkPass, TorchPass and TorchSnap.
LinkPass: Rerouting Around Network Failures
LinkPass reroutes network traffic around failed network links.
In large GPU clusters, network connectivity is essential because distributed workloads need to exchange data between processors. A failed link can disrupt communication and affect the progress of an entire job.
By routing traffic around failed links, LinkPass aims to reduce the impact of network faults and keep workloads running.
LinkedIn has deployed LinkPass across its AI infrastructure. According to the company, this deployment prevents tens of thousands of GPU-hours of downtime each month.
TorchPass: Moving Workloads Away from Failing GPUs
TorchPass is designed to move workloads from failing GPUs to healthy ones without requiring a complete restart.
This approach is intended to reduce the amount of useful work lost when hardware begins to fail. Instead of allowing a component problem to trigger a broader interruption, the software helps the workload continue on functioning hardware.
Together AI is bringing TorchPass to its GPU clusters, according to the article.
The deployment reflects demand for reliability software among companies operating GPU infrastructure for AI development and production workloads.
TorchSnap: Checkpointing Without Code Changes
Clockwork has also launched TorchSnap, a checkpointing technology designed to protect distributed AI workloads without requiring changes to training code.
Checkpointing saves a workload's state so that computation can resume from a preserved point if an interruption occurs. For distributed AI systems, capturing state across multiple nodes can be challenging because the components must be represented consistently.
TorchSnap is designed to capture the state of distributed jobs across multiple nodes. The company also says its faster application checkpoints can help reinforcement-learning systems distribute updated model weights to inference replicas more quickly.
These capabilities target a common limitation of traditional recovery approaches: saving progress and restarting a job can introduce delays, particularly when the workload involves many interconnected GPUs.
Founded on Stanford Research
Clockwork.io was founded in 2018 by Balaji Prabhakar, Yilong Geng and Deepak Merugu, drawing on research at Stanford University. VMware co-founder Mendel Rosenblum serves as the company's chief scientist.
Prabhakar is a Stanford professor whose research focuses on computer networks and data-centre systems. Geng's Stanford research produced the Huygens clock-synchronisation technology that became foundational to Clockwork's platform. Merugu previously co-founded Urban Engines, which was acquired by Google.
The company is now led by CEO Suresh Vasudevan, who previously led Sysdig and Nimble Storage. At Nimble, he took the company through an initial public offering and its eventual acquisition by Hewlett Packard Enterprise. He has also held senior leadership positions at NetApp.
The leadership team's experience spans computer networking, distributed systems, enterprise infrastructure and the commercial scaling of technology companies.
LinkedIn, Together AI and WhiteFiber Expand Adoption
Clockwork.io's latest funding comes alongside reported deployments and expansion plans involving several AI infrastructure operators.
LinkedIn has deployed LinkPass across its AI infrastructure and says the software prevents tens of thousands of GPU-hours of downtime every month.
Together AI is bringing TorchPass to its GPU clusters, while WhiteFiber is expanding Clockwork's software across its global GPU-as-a-service infrastructure.
These deployments provide examples of how fault-tolerance software can be applied across different AI infrastructure environments. They also offer Clockwork opportunities to demonstrate the value of its technology under real operating conditions.
The company intends to extend its platform across AI training, inference and reinforcement learning, workloads that have different performance and reliability requirements.
Competing for a Place in the AI Infrastructure Stack
AI infrastructure investment has accelerated as businesses expand their use of advanced models and AI applications.
The article cites Gartner's forecast that global AI spending will reach $2.7 trillion in 2026, growing 49.5% year over year, with AI infrastructure representing the largest spending category.
Companies such as Together AI and Crusoe are expanding the computing capacity available to AI developers, while Nscale is investing in full-stack AI cloud infrastructure.
Clockwork operates at a different layer of this market. Rather than primarily supplying GPUs or data-centre capacity, it focuses on helping infrastructure providers get more useful work from the computing resources they already operate.
That distinction matters because adding more GPUs does not automatically eliminate the operational problems associated with large clusters. Hardware failures, network interruptions and recovery overhead can still reduce the amount of productive computation delivered.
If fault-tolerance software can reduce those interruptions, infrastructure providers may be able to improve utilisation and limit the waste associated with restarting workloads.
What the $31 Million Funding Will Support
The $31 million round brings Clockwork.io's total funding to $73 million. Premji Invest, Wing Ventures and Seligman Ventures co-led the round, while NEA and e& Capital participated as existing investors.
The company plans to use the funding to roll out its fault-tolerance platform more broadly across AI training, inference and reinforcement learning.
Its next challenge will be expanding adoption across increasingly diverse GPU environments while demonstrating that its software can reliably handle the failures encountered in production.
As AI infrastructure grows more expensive and distributed workloads become more demanding, reliability is becoming an important part of the computing equation. Clockwork.io is betting that keeping GPUs productive through failures can deliver meaningful value to enterprises and AI cloud providers.
The company's reported deployments at LinkedIn, Together AI and WhiteFiber give it a starting point. Its longer-term opportunity depends on how effectively it can scale those capabilities across the wider AI infrastructure market.
Have a Funding Round or Exciting Update to Share?
Submit your press release to get featured on WorkNation and reach founders, investors, and tech leaders.